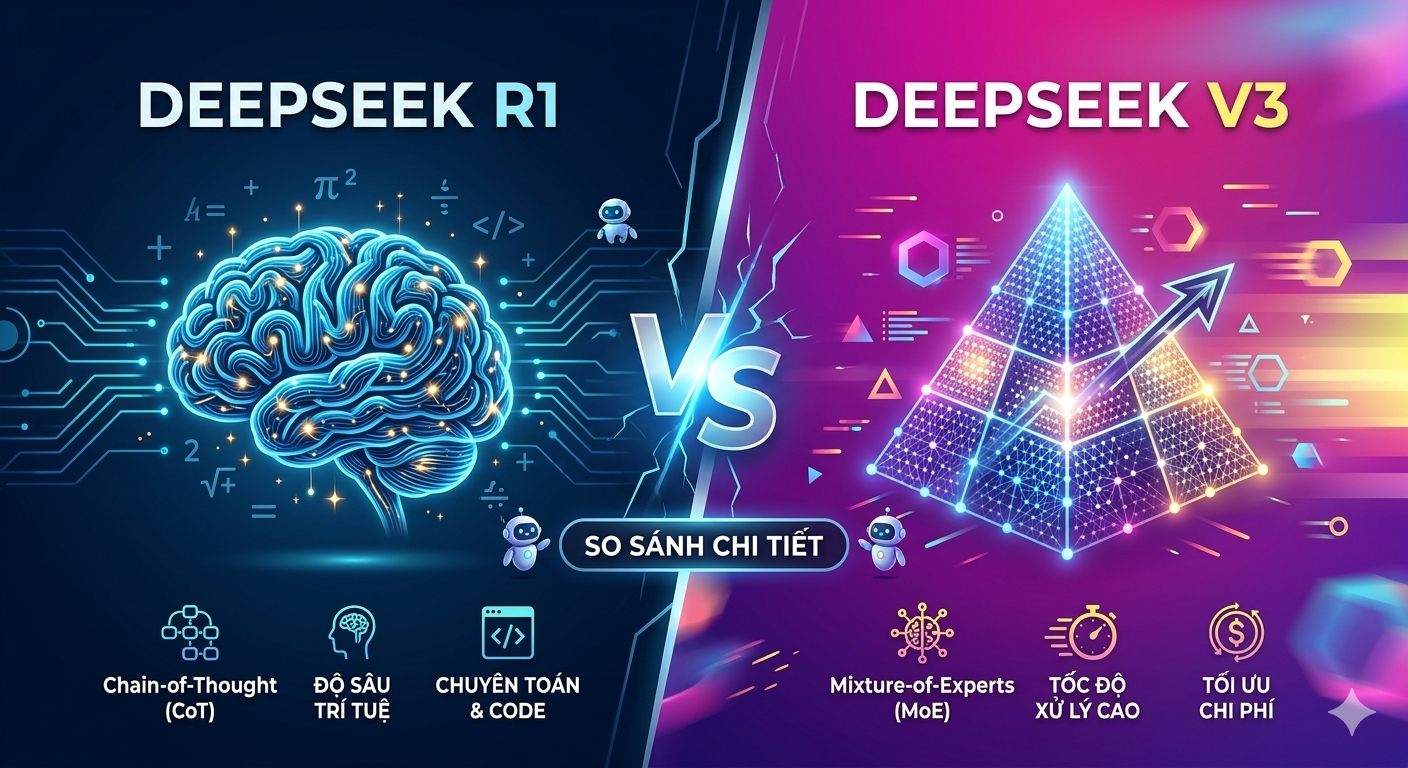
DeepSeek R1 is a reasoning-focused large language model (LLM) developed by DeepSeek, an AI research company founded in China in 2023. Unlike standard chat models that generate responses instantly, R1 is designed to think through problems step by step before answering — a process called chain-of-thought reasoning.
The model has 671 billion parameters in total, but only 37 billion are active during any single inference pass, thanks to a Mixture of Experts (MoE) architecture. This makes it far more efficient than its total parameter count suggests. It was released on January 20, 2025, under the MIT License — meaning anyone can download, modify, and even commercialize it freely.
R1 was trained using reinforcement learning (RL) without relying heavily on supervised fine-tuning. Specifically, it uses a technique called Group Relative Policy Optimization (GRPO), which allows the model to develop its own reasoning strategies through trial and reward — rather than being taught explicit reasoning paths by human annotators.